Shengyuan Medical focuses on Medical Data Governance, Data Annotation, Disease-Specific Models & Agents, Data Transaction Four core business lines, with in-house medical devices as a compliant entry point for real-world data, building a complete loop from data ingestion to clinical application.
 AI + MEDICAL DATA
Data services delivered within the following regulatory and requirement frameworks
Medical data is not scarce; what is scarce is data that is usable, trustworthy and authorisable. We start from governance and annotation, move on to models and agents, and finally complete data transactions under compliance.
For healthcare institutions and research settings we establish consistent definitions, quality standards and security boundaries, turning medical data scattered across devices, systems and archives into usable, trustworthy and traceable data resources.
For imaging, waveforms, text and structured clinical records, we establish medical annotation standards and multi-round quality-control processes, providing high-quality reusable annotated data for disease-specific model training.
We build data models and knowledge systems around specific disease areas and package them as medical agent applications that clinicians, researchers and institution operators can call directly, so data capability lands in real settings.
With compliance and authorisation in place we connect data suppliers and users, supporting data product scoping, compliance assessment and data transaction — moving medical data from a dormant resource to an exchangeable, deliverable data element.
* Medical data involves personal privacy and sensitive information. We provide these services only within the scope of compliant authorisation, de-identification and the agreed purpose, and raw data never leaves its domain. The subject matter of any transaction is a compliance-assessed data product or service capability, governed by the agreement between the parties, regulatory requirements and the rules of the compliant data exchange.
Data capabilities only have value when they flow. Crowd Platform opens annotation tasks to people with professional expertise, addressing 'how data is processed well'; the Data Transaction section connects the two sides of supply and demand, addressing 'in whose hands the data becomes useful'.
Open to physicians, medical students and professional annotation talent: real-name and qualification verification, an online annotation workspace, multiple rounds of quality control and per-task pay. Professional judgement is priced accurately and data quality is strictly safeguarded.
Providers and users of data register their respective needs and resources. AI first performs smart supply-demand matching and outputs a candidate list with matching reasons; professional consultants then provide human follow-up to turn the matching results into a compliantly deliverable proposal.
Pricing and acceptance standards are disclosed before a task is claimed, levels are determined by actual annotation quality, and reward details can be checked item by item.
Every annotation can be traced back to the person who completed it and their verification level, forming a verifiable work record.
No transaction without a scenario and no buying or selling of raw data; delivery is completed in a secure and trusted environment with record-keeping.
From data ingestion to a self-controlled technology kernel, the eight-layer architecture defines clearly where data comes from, how it is processed, how it is used and where its boundaries lie — the precondition for compliant use of medical data.
Unified ingestion of multi-source heterogeneous data — medical devices, hospital systems, imaging and waveforms — with structured and standardised mapping.
Multi-source heterogeneous · structured mappingConsistent definitions and quality standards covering cleansing, classification, de-identification and end-to-end traceable audit.
Core business 01Medical annotation standards, expert review and multi-round QC producing high-quality annotated data ready for model training.
Core business 02Data asset catalogue, ownership and authorisation management, compliance assessment, plus data product registration and data transaction.
Core business 04Data models, knowledge bases and efficacy assessment for specific disease areas, supporting personalised recommendations.
Core business 03Agent applications for clinicians and institutional operations: clinical assistance, report interpretation, follow-up management and operational analytics.
Core business 03A unified agent orchestration and capability encapsulation layer that wraps data and model capabilities into safely callable business interfaces.
Capability encapsulation · orchestrationA self-controlled core runtime supporting deployment in domestic-stack environments, on-premises data and multi-tenant isolation.
Domestic-stack ready · data stays on-premisesClinical care generates data, and data feeds back into care. We capture every episode as a structured asset, then turn those assets into better tools in clinicians' hands.
← Swipe to see the full chain →
Our data comes from two sources: real-world clinical data co-built with partner hospitals, and structured parameter records generated in parallel at the device level during treatment. Unlike retrospective entry, device-side data is structured as it is produced — parameters, duration, dose and follow-up indicators correspond one to one — so it is inherently reproducible, traceable and verifiable. This is the first guarantee of data asset quality.
Diagnosis, examination, laboratory and follow-up records from partner hospitals enter the governance pipeline after alignment to the unified subject model and terminology.
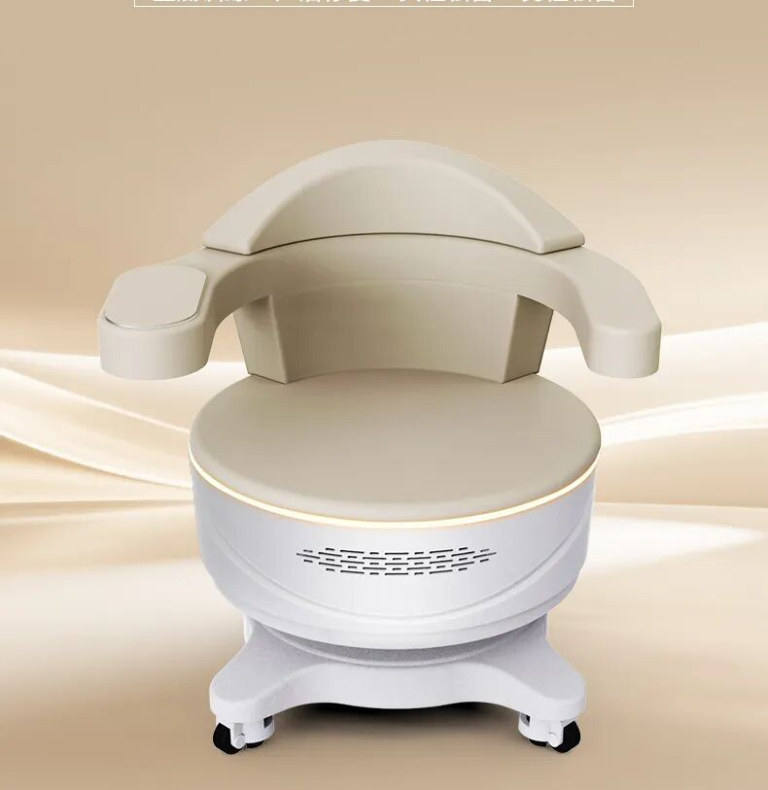
Treatment parameters, course stage and device exposure are recorded in parallel during treatment and can be linked precisely to follow-up outcome indicators.
We build compliance into every layer of the data chain: who may see it, how much they see, what it is used for and how it is traced must all have a clear answer.
We collect only fields directly relevant to care and research purposes, avoiding over-collection.
Purposes and scope of use are defined explicitly; any third-party use requires authorisation.
Sensitive fields are de-identified, access is isolated by role and scenario, and raw data never leaves its domain.
Collection, transfer, annotation and use are all logged, forming a traceable operation record.
We prefer verifiable facts: the architecture layers, the number of laws, the hard-blocked data categories, and the automated tests behind each one.
Eight layers decoupled from the bottom up; the seven product layers A–G share a single H kernel, and kernel capabilities must not be reimplemented inside any layer.
Shared kernel, triple gates, no anonymous fallback, a single evidence chain — all enforced by tests and static analysis, not by promises in documents.
Fourteen categories of data — patient identifiers, human genetic resource data, raw imaging and waveforms and others — are hard-blocked at the architecture level and cannot be unlocked by any workflow approval.
For the full list of these capabilities, what has been validated and what is still outstanding, see Technology and About Us.
First establish entry points through real data sources, then build data assets through governance and annotation, and finally bring disease-specific models and agents into daily clinical practice.
If your institution, research organisation or company would like to work with us on medical data governance, data annotation, disease-specific models and agents, or data transaction, please get in touch. Product and channel partnerships for medical devices are equally welcome.